Executive Abstract
Why monolithic backends crumble under multimodal AI traffic, and how event-driven microservices ensure microsecond inference delivery.
1. The Computational Profile of Modern AI Workloads
Standard web applications are I/O bound: waiting on relational databases or external REST endpoints. Large language models and diffusion pipelines, conversely, are compute and memory-bandwidth bound, demanding dedicated GPU tensor cores and sub-millisecond inter-node communications.
Attempting to host heavy model inference inside conventional HTTP application servers quickly leads to thread pool starvation, head-of-line blocking, and catastrophic latency spikes under moderate load.
Key Architectural Takeaways:
2. Real-Time Streaming and Edge Caching
Enterprise users expect immediate time-to-first-token (TTFT) metrics below 200ms. Achieving this requires HTTP chunked transfer encoding and Server-Sent Events (SSE) combined with distributed Redis semantic caching.
By caching embedding vectors of common queries, systems can serve semantically identical requests from cache in under 5ms, offloading up to 40% of costly GPU compute cycles.
Strategic Synthesis
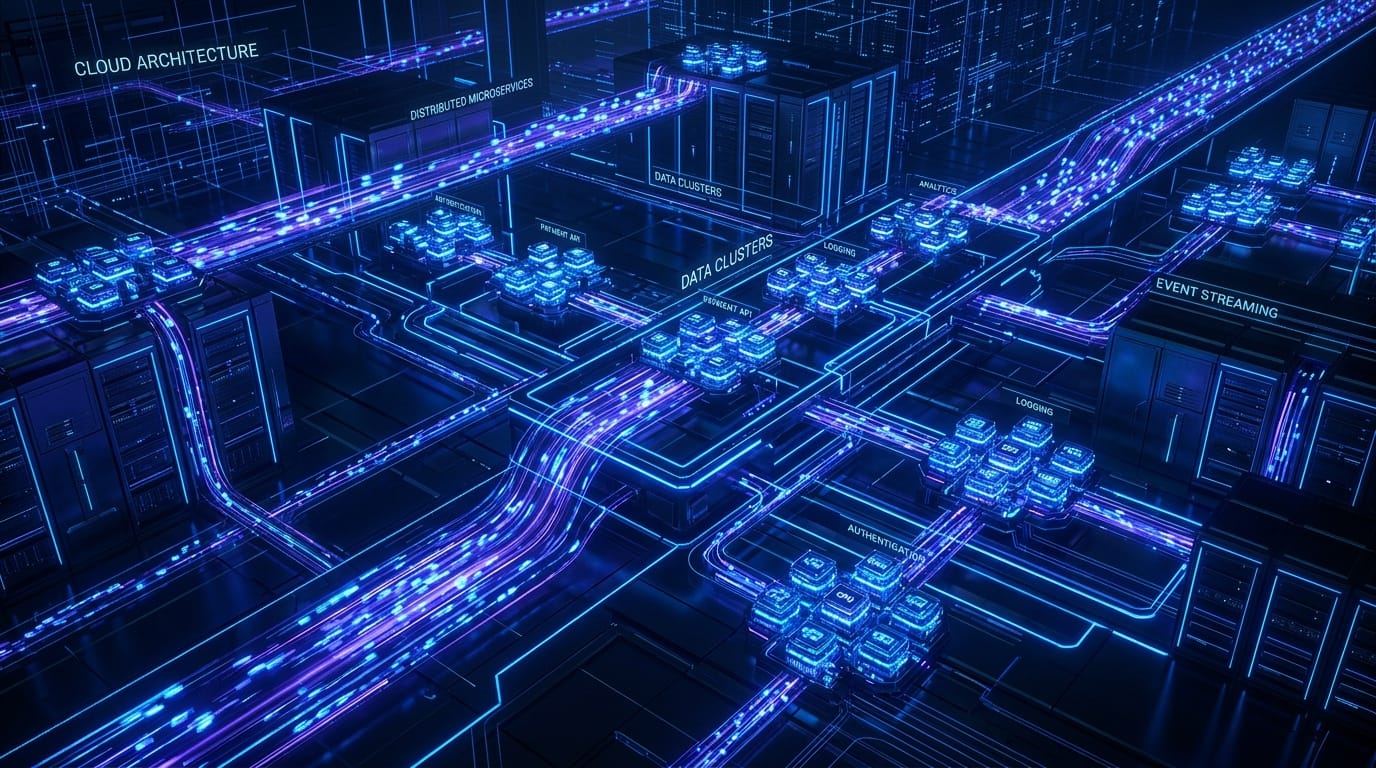
A resilient software architecture for artificial intelligence requires disciplined separation of concerns: ultra-fast edge routing, distributed semantic caching, and autoscaled GPU tensor fabrics orchestrated through Kubernetes.